Headroom

The context compression layer for AI agents

77,036
Stars
5,977
Forks
226
Contributors

Compress everything your AI agent reads — tool outputs, logs, RAG chunks, files, and conversation history — before it reaches the LLM. Same answers, fraction of the tokens.
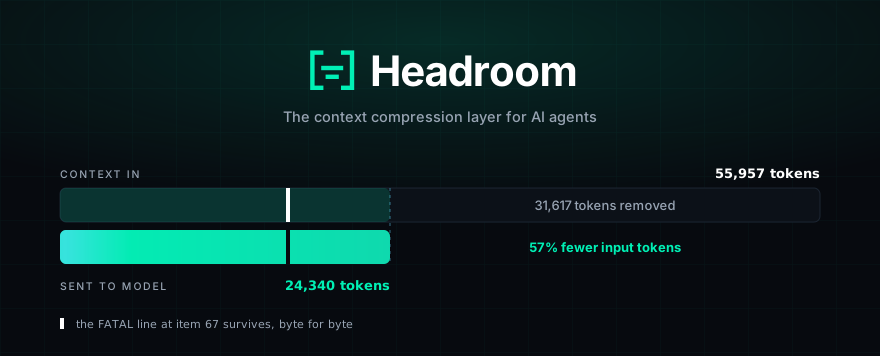
Headroom compression demonstration

What it does

Headroom runs locally on your machine; no prompt or file content is sent anywhere to be compressed.

Library

compress(messages) in Python or TypeScript, inline in any app.

Proxy

headroom proxy --port 8787, zero code changes, any language.

Agent Wrap

Wrap Claude, Codex, Grok, Copilot, Cursor, Aider and more in one command.

MCP Server

Headroom tools for any MCP client with headroom_compress, headroom_retrieve, headroom_stats.

Cross-agent Memory

One shared store across Claude, Codex, Gemini and Grok, with automatic deduplication.

Reversible (CCR)

Originals are cached locally and retrieved on demand when the model needs them.

Proof

Real-world compression scenarios measured with provider tokenizers

Scenario Before After Saved
Code search (100 results) 17,199 13,597 21%
SRE incident debugging 55,957 24,340 57%
Codebase exploration 58,801 33,895 42%
GitHub issue triage 46,067 32,429 30%

Get started in 60 seconds

Install Headroom and start saving tokens immediately

1 — Install
uv tool install --python 3.13 "headroom-ai[all]"
pip install "headroom-ai[all]"
npm install headroom-ai

2 — Pick a mode
headroom deploy
headroom wrap claude
headroom proxy --port 8787

3 — Check it
headroom doctor
headroom perf
headroom dashboard
Start Compressing